Previous Release Updates
Forcepoint DSPM 4.1.4 Hotfix
Posted on Aug 31, 2026
Improved handling of datasource rate limiting for cloud connectors
The Generic Connector now detects HTTP 429 (Too Many Requests) responses from OneDrive, SharePoint Online, and Google Drive and automatically pauses requests to the affected connector and
credential. The pause honors the datasource's Retry-After guidance where provided, falling back to a configured per-connector interval otherwise. During the pause, DSPM returns a
429 with Retry-After to callers rather than forwarding traffic to the datasource. This reduces failed scans and avoids compounding throttling during periods of heavy datasource
load.
Resolved issues
Posted on Aug 31, 2026
Improved automatic throttling recovery for Microsoft connector content downloads to prevent repeated request failures and scans from getting stuck during datasource throttling.
Forcepoint DSPM 4.1.3 Hotfix
Posted on Aug 17, 2026
- Fixed an issue where OneDrive/SharePoint discovery scans could be interrupted when Microsoft Graph API throttling occurred.
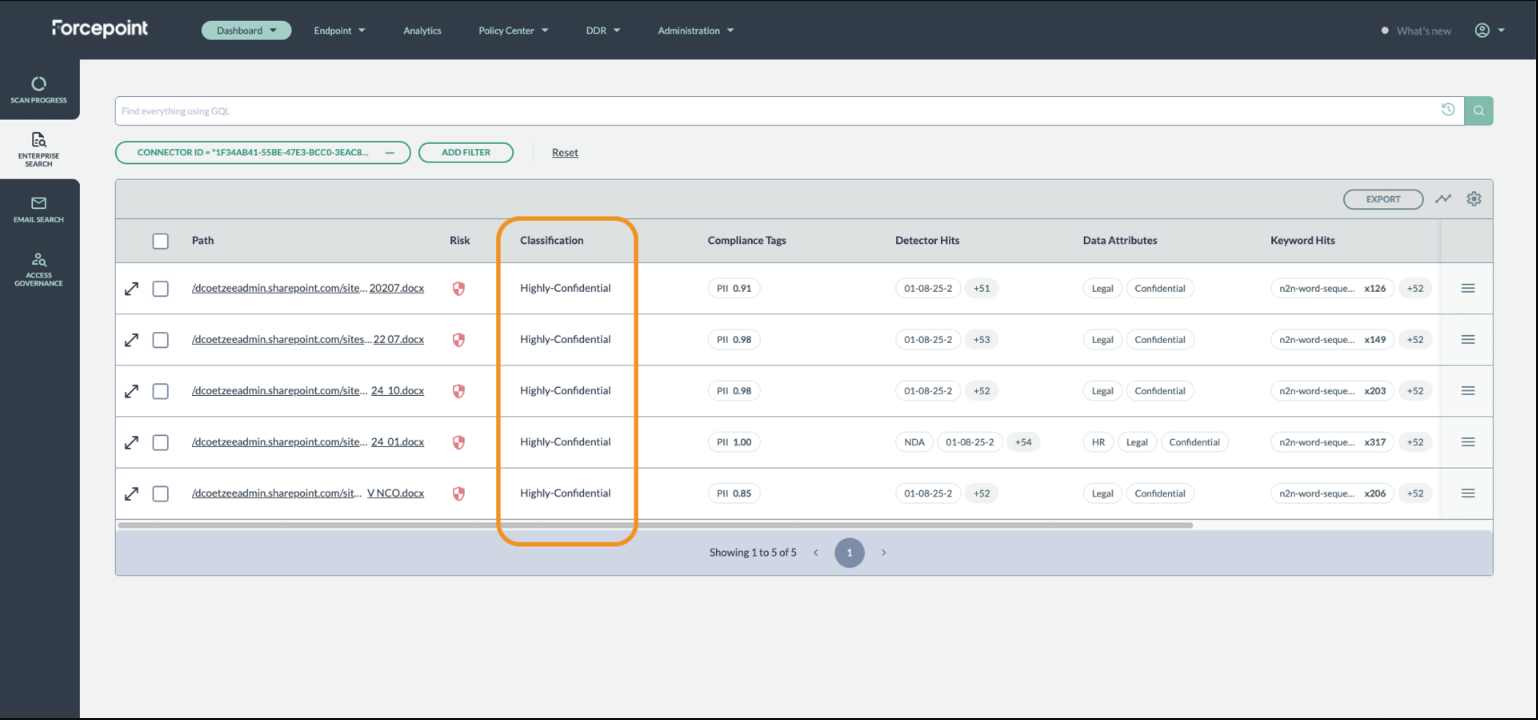
- Enterprise Search now displays the classification tag alias rather than the underlying tag name after a manual classification edit.
- Corrected the externally shared flag for the SharePoint Online service account permission, which was incorrectly reported as externally shared.
- The SMB connector now validates file creation timestamps. Files from servers that return no creation time no longer show invalid dates and instead uses the last modified or accessed time.
- Fixed the Enterprise Search results table showing null or incorrect created/modified dates. Stored data and exports were always correct; this was a display-only issue.
- Restored the Trustee Name and Trustee Login Name columns in Enterprise Search, they populate correctly in both the on-screen table and the export.
- Fixed a race condition in discovery that could cause it to become stuck under heavy throttling as observed for OneDrive and SharePoint Online scan.
- Corrected the retry classification for throttling and lock errors (423/429); the number of retries was modified to correctly handle the throttling errors.
- Added exponential backoff and recovery mechanism to prevent scan errors and scans left open indefinitely.
- SMB tagging now records file audit log events as hard tagging events, matching the fact that SMB supports hard tagging only.
- Fixed manual classification edits inserting a stray apostrophe into hyphenated labels (for example, Highly Confidential). Labels are now stored exactly as selected.
- The "Incomplete" discovery status reflected a temporary display state that appeared while the discovery scan was still in progress. It has since been updated to display as "In Progress" for clarity.
- Fixed the DLP Rule Names column in the Enterprise Search export. It no longer shows an unreadable object or populates entries for files without a DLP match. The column now displays the rule name or remains empty when no rule matches.
- Improved FDC agent connection reliability when PDF configuration is disabled.
Forcepoint DSPM 4.1
Posted on July 07, 2026
Release Summary
Forcepoint DSPM is undergoing a focused evolution across the past few releases — from a foundational scanning architecture toward a fully unified, self-service-driven data security platform. DSPM 4.0 delivered high-throughput classification out of the box by combining DLP classifiers with the AI Mesh engine.
DSPM 4.1 takes the next meaningful step toward operational self-sufficiency, introducing self-service taxonomy label customization — giving organizations direct control over how their data is classified — alongside key reliability improvements: proactive disk back-pressure notifications, Admin Audit Logging for compliance-driven governance visibility, and Scan Status enhancements. The below sections describe the new features and enhancements delivered in DSPM 4.1.
Admin Audit Logging Enhancement
DSPM 4.1 now includes comprehensive Admin Audit Logging capabilities, a critical feature for organizations implementing DSPM with strict compliance and governance requirements. This enhancement addresses the audit trail and forensic investigation needs identified by enterprise customers across banking, financial services, and government sectors.
- Who performed the action (user email/ID).
- What was changed (module, functionality, and specific values).
- When the change occurred (date and timestamp).
- How the value changed (before/after state with complete change lineage).
For more information, refer to the Admin Audit Logging Enhancement section.
Tag Alias Support
DSPM 4.1 now supports tag aliases for data source taxonomy definitions. This feature enables administrators to display user-friendly alternative names for out-of-the-box (OOTB) taxonomy tags, reducing confusion and improving the user experience.
Key Features
- Files classified after feature release display defined tag aliases in relevant fields.
- Files classified before this release continue to display tag names.
- Administrators see tag aliases in pattern creation and manual classification dropdowns.
- Tag name is shown as fallback when alias is not defined.
- Field names and columns remain unchanged.
- GQL queries and basic filtering continue to work by tag name.
- Fully backward compatible - existing integrations and APIs unaffected.
To watch the demo video, click here
Scan Status Tracking Improvements
Enhanced scan status tracking provides real-time visibility into classification stage progress. Users now have accurate, up-to-date information about scan classification status across scan configurations, preventing confusion and accidental duplicate scans.
- Classification Stage Status Visibility.
- Improved Status Display: Scan configuration status now accurately reflects classification stage progress.
- Duplicate Scan Prevention.
- Smart Alerting: Users receive a clear alert when attempting to start a new scan for a configuration that has associated scans still in classification progress.
For more information, refer to the Scanning Data Sources section.
Securing Exchange On-Premises Through Data Discovery, Classification and Response
DSPM 4.1 now delivers an integrated sensitive data discovery, classification, and response workflow for Exchange On-Premises environments. This initiative addresses critical compliance and security challenges by enabling organizations to rapidly discover sensitive data, automatically classify it with high accuracy, and execute coordinated response actions.
- Faster Compliance: Reduce time-to-remediation from weeks to hours.
- Risk Visibility: Executive dashboards for sensitive data inventory and exposure.
- Scalability: Automated workflows eliminate manual classification bottlenecks.
- Regulatory Confidence: Complete audit trails for GDPR, CCPA, HIPAA, and internal compliance requirements
For more information, refer to the Exchange On-Premise section.
Introducing Synergy Light: A Deployment Option for FDC-Only Customers
This release introduces synergy light, a new lightweight Synergy deployment option built for FDC-only (Forcepoint Data Classification) customers who do not need the full AI mesh classifier stack. Synergy light runs only the DLP classifier engine, following the same pattern as the existing dspmlight deployment, and is delivered as a dedicated product code rather than a label to ensure full feature-flag compatibility.
Synergy light, provides a stripped-down Synergy deployment that removes the AI mesh classifiers to reduce the overall resource footprint. Using a dedicated product code (instead of a label) ensures clean feature-flag handling and deployment consistency.
- Lightweight Synergy deployment reduces resource consumption by removing AI mesh classifiers.
- DLP policy-based content classification for endpoint agents connecting to a synergy light cluster.
- End-to-end file classification through the DLP engine, with policy group batching to support large policy sets.
- Clear sizing guidance for on-premises synergy light deployments across relevant license configurations.
- Lower infrastructure cost and footprint for customers who only require DLP classification.
- Faster, simpler deployments tailored to FDC-only use cases.
- Consistent classification behaviour aligned with the established dspmlight pattern.
Teradata Structured Data Connector
DSPM 4.1 now includes native support for Teradata, a widely used enterprise data warehouse platform. This new structured data connector enables organizations to discover, catalog, and classify sensitive data stored in Teradata databases as part of their comprehensive data security and compliance programs.
- Seamless Teradata Integration
- Comprehensive Metadata Discovery
- Data Classification and Governance
- Minimal Database Permissions
- Reliability and Performance
For more information, refer to the Teradata section.
Oracle Exadata Support for Structured Data Discovery
The Oracle structured data connector now works with Oracle Exadata environments. Rather than introducing a separate connector, Exadata support is built into the existing Oracle connector, so there's no new setup process to learn. To accommodate the Wallet-based (mTLS) authentication typically used in Exadata deployments, a new Oracle Wallet authentication toggle has been added to the credentials configuration.
For more information, refer to the Oracle section.
SAP ASE Structured Connector
Forcepoint DSPM now includes support for SAP ASE (Adaptive Server Enterprise),formerly Sybase ASE as a scannable data source, extending the same level of discovery, classification, and risk analysis that are already provided for other supported databases. With the SAP ASE connector, Forcepoint DSPM can discover, classify, and monitor sensitive data stored in SAP ASE databases.
For more information, refer to the SAP ASE section.
Smarter Disk Space Protection with Monitoring, Alerts, and Automatic Safeguards
Disk Space Monitoring and Alerts
Forcepoint DSPM keeps a constant watch on available disk space. Whenever free space falls below a set threshold, administrators get an in-product notification urging them to act right away. Should disk space run out entirely, select product features are paused temporarily until enough space becomes available again.
Disk-Pressure Circuit Breaker
DSPM now guards against disk-exhaustion failures through a platform-wide disk-pressure circuit breaker. Once storage usage exceeds a configurable threshold, the system automatically halts new and deferrable tasks to keep the platform stable, observable, and recoverable — rather than continuing to take on work until the disk fills up and the cluster fails.
- Eliminate surprise outages — the platform self-protects instead of crashing when the disk is full and stays responsive and readable.
- Self-service recovery — cancel scans or delete old configurations to free space without contacting support.
- Less downtime and disruption — proactive protection means fewer incidents, faster mean-time-to-recovery, and a lighter support burden.
For more information, refer to the Problems due to inadequate resources section.
Database Scan Performance and Scale
- Scan much larger databases: DSPM can now scan databases with up to 4 million columns, 200,000 tables, and 10,000 users in a single pass — handling enterprise-scale data sources that previously couldn't be processed, with no additional infrastructure required.
- Faster, more reliable scans: Improved data streaming and processing deliver more stable, memory-efficient scans, so large scans complete reliably without interruption.
- Broader connector improvements: Faster column scanning and improved error recovery for Databricks and Snowflake, so a single timeout no longer interrupts an entire scan.
- Greater accuracy: More accurate user and permission reporting, including fixes for missing table permissions on Oracle, DB2, and Microsoft SQL Server, and more consistent results across connectors.
| ID | Fix |
|---|---|
| DSPM-7042 | Fixed an issue that prevented SharePoint Online scans from discovering files when specific permission types, including shared links and group permissions, were present. |
| DSPM-1516 | Implemented parallel processing for pattern-matching (Regexes) to improve performance. |
| DSPM-1515 | Fixed an issue where classification tags were not applied when tagging PDF files. |
| DSPM-1234 | Fixed an issue where classification results could be inconsistent when multiple classification rules matched the same file. |
| DSPM-1226 | Fixed file lineage lookup functionality that was broken for Google Drive, Box, Dropbox and Slack. |
| DSPM-1225 | Fixed an issue where persistent tagging failed for Microsoft Visio files. |
| DSPM-1115 | The file tagging action, previously unavailable on the Data Sources page, has now been restored. Users can now tag files directly from the Data Sources interface without needing to navigate to the Enterprise Search page. |
| DSPM-1114 | [For Cloud DSPM Customers Only] Removed duplicate detector menu item from DSPM console left navigation panel. |
| DSPM-1044 | Fixed SharePoint on-prem sub-container loop causing same folders to be rescanned indefinitely. |
| DSPM-973 | Users can now create, save, and view up to 30 departments in the Policy Center UI—increased from the previous 20-department limit. |
| DSPM-965 | Fixed Email Notification validation functionality. |
| DSPM-881 | Files on SMB shares that contain sensitive content and grant write permissions (e.g., Full Control, Modify, or Read & Write) to multiple users are now correctly classified as MEDIUM risk, in alignment with the documented risk-level criteria. Previously, these files were incorrectly classified as LOW risk. |
| DSPM-848 | Restored Confidence scores to Compliance Tags and Data Attributes in CSV and JSON exports. |
| DSPM-845 | Fixed content extractor timeout overrun issue causing excess failures in content extraction. |
| DSPM-784 | Fixed an issue where trustee scans remained stuck in the In Progress state after transient errors occurred. Scans now correctly log errors, retry processing, and update their status to FAILED or INCOMPLETE as appropriate. |
| DSPM-324 | Fixed incorrect SMB Risk Classification for broad access permissions. |
Forcepoint DSPM 4.0
This section lists the new features and enhancements for the Forcepoint DSPM solution included in the current release.
Release Summary
DSPM 4.0 ships several features across two themes: a comprehensive classification stack updates to include Forcepoint DLP Classifiers and a set of independent capabilities spanning infrastructure resilience, enterprise secrets management, a new data-source connector, and platform identity consolidation.
Customers get faster classification by default, can connect DLP classifiers to drive outcomes, and can trace every classification verdict back to the specific rule that produced it.
Additionally, there are independent features that extend DSPM into Databricks environments, bring enterprise credential vaulting through CyberArk, and consolidate Cloud DSPM identity onto the Forcepoint Platform IdP - which in turn enables role-based access control for the first time in Cloud DSPM.
The Classification Stack
Five features that work together to make DSPM classification faster, more transparent, and easier to explain to customers and auditors.
- Classifier Improvements
What it does:
DSPM 4.0 provides an improved out-of-the-box classification pipeline with a new lightweight service built on a proven DLP engine. Classification pipeline is fully parallelizable, runs with low CPU and memory overhead, and is observable as a dedicated microservice. The result is dramatically faster classification from day one, without requiring data-science-led tailoring.
The existing AI Mesh path remains available for those who desire it. Customers can choose to upgrade to the new classification system by discussing with their Forcepoint customer service representative.
The feature is enabled through the cluster configuration in Rancher (product code for On-Premises and add-on for SaaS). If not enabled, then the existing flow with AI Mesh and Detectors stays active.
- DLP Classification Flow
What it does:
The DLP Classification Flow connects customer-configured DLP policies directly to the per-file classification engine. When a scan runs, DSPM evaluates each file against the selected DLP policies using the optimized multi-threaded classifier. Pattern matching can override classification model outcomes when a pattern hit occurs, giving customers fine-grained control over how specific content types are classified. Content and path detectors continue to surface findings but no longer drive the top-level classification label.
Customer benefits:- Customers can select the DLP policies that matter to their business and see classification outcomes driven by those policies, not by an opaque model.
- Every classification outcome traces back to specific DLP rules and policies, giving customers a clear audit trail.
- Pattern-match overrides allow security teams to ensure that high-priority content types are never misclassified, regardless of model confidence.
- Eliminates the most common support escalation category: unexplained classification verdicts.
Customers who have not enabled DLP classification feature will continue to see AI Mesh-driven outcomes unchanged.
- New UX to Explain Classification Outcomes
What it does:
DSPM 4.0 introduces the Classification Model page, a redesigned surface that shows customers exactly why each file received its classification label. A Sankey-style visualization maps DLP policies / Detectors to classification outcomes, replacing the previous AI Mesh page with a transparent, traceable view. Terminology is aligned with the DLP policies, Detectors and Taxonomy pages, so customers work within a single vocabulary across the product.
Customer benefits:- Customers can trace any classification outcome back to the specific DLP rule or pattern that produced it, turning a black box into an auditable process.
- Support and security teams can resolve classification disputes in minutes rather than escalating to the support team.
- Unified vocabulary across the Classification Model page and Detectors / DLP policies pages removes confusion between overlapping terms.
- Onboarding Flow Redesign
What it does:
The redesigned onboarding flow is built to seamlessly configure the connector and observe classification results in a few minutes.
Customer benefits:- Classification can be configured as part of the initial scan setup - no separate workflow, no hunting for the right menu.
- The Quick Start guide is updated for 4.0, giving new customers a clear path from sign-in to their first classification results.
- Eliminates the highest-frequency complaint from new customer onboarding feedback.
Note: Existing tenants are not affected by the onboarding flow changes - the redesign applies to new tenant provisioning only. Existing users will see the updated dashboard auto-refresh behavior when they log in after the upgrade.Additional Features
Three capabilities that independently extend DSPM's reach, resilience, and enterprise integration story.
- Scan Pipeline Hardening
What it does:
DSPM 4.0 includes a comprehensive scan pipeline hardening initiative targeting the root causes of the most common customer-reported scan reliability issues. Changes include right-sized memory and CPU defaults across all pipeline services, corrected timeout alignment between the scan orchestrator and downstream services, OCR and Content Extractor performance profiling, and proactive alerting for cataloging and classification throughput drops.
Customer benefits:
- Memory limit increases are no longer required in the common cases.
- Proactive throughput alerts give operations teams early warning of classification or cataloging drops.
All hardening changes are applied automatically with the 4.0 upgrade - no additional configuration is required.
- CyberArk Password Manager Integration
What it does:
DSPM 4.0 introduces native integration with CyberArk's Credential Provider (CP) for just-in-time secret retrieval. Instead of storing credentials directly in DSPM, administrators reference a CyberArk AppID, Safe, and Object. DSPM retrieves the credential at scan time and never persists it. Secret rotation in CyberArk is fully transparent to DSPM - when a credential is rotated, the next scan automatically picks up the updated value without any reconfiguration.
Customer benefits:- DSPM never stores connector credentials, eliminating a significant audit and compliance risk for security-conscious enterprise customers.
- Customer security teams retain full ownership of all secrets in their existing CyberArk vault, with no credential duplication.
- CyberArk's audit log captures every credential access by DSPM - which connector, which reference, and when providing a complete access trail.
- Secret rotation is seamless: credentials can be rotated in CyberArk at any time without updating DSPM configuration.
- The Test Connection feature validates credential references with a masked preview before committing to a full scan configuration.
- Warm credential retrieval targets under 100ms at the 95th percentile; cold retrieval targets under 700ms.
CyberArk integration is opt-in. Existing connectors continue to use their current credential storage unless an administrator explicitly migrates them to CyberArk references. Migration requires a CyberArk CP deployment accessible from the DSPM host - the exact deployment topology (server-local vs sidecar) is being finalized before GA. Customers can choose to upgrade to the new classification system by discussing with their Forcepoint customer service representative.
For detailed information, refer to the CyberArk Password Manager Integration section.
- Databricks Unstructured Connector
What it does:
DSPM 4.0 adds connectors for Databricks - a Unity Catalog connector covering catalogs, schemas, volumes, and files; and a Workspace connector covering notebooks, repositories, clusters, jobs, and SQL warehouses. File content within Databricks Volumes is scanned for sensitive data; Notebooks are scanned for sensitive content in source code. Authentication uses Personal Access Tokens (PAT) over TLS 1.2+. The connectors are validated against DSPM's Scan Progress, Enterprise Scan, Access Governance, Analytics, Incidents, and Live Events surfaces.
Customer benefits:- Security and compliance teams gain visibility into sensitive data residing in Databricks - a high-priority enterprise data source for ML and analytics workloads.
- Sensitive content in Databricks Volumes, previously invisible to DSPM, is now discoverable and classifiable.
- Move-Selected-File remediation works between Databricks and other DSPM-connected repositories.
- Metadata extraction covers all Databricks object types, enabling access governance reporting alongside data sensitivity findings.
The Databricks connectors are new additions in 4.0 and are available to all tenants after upgrading. Administrators configure connections using a Databricks PAT and workspace URL. No changes are made to existing connectors or scan configurations during the upgrade.
For detailed information, refer to the Setting up Unity Catalog Datasource Connector and Setting up Workspace Datasource Connector sections.
Forcepoint DSPM 3.4
- Snowflake DSPM Connector Support for Structured Data
Customers can discover, scan, classify, and risk-assess structured data in Snowflake's AI Data Cloud through a new dedicated connector.
For detailed information, refer to the Snowflake section.
- Multi-proxy Support
Multi proxy support enables each connector to operate with its own dedicated proxy configuration instead of relying on a single global proxy. This allows every connector to meet its individual requirements, security policies, and network routing preferences. For example, the Azure AD connector can use one proxy while the OneDrive connector uses another. Multi‑proxy support is enabled across all cloud‑based and on‑premises connectors.
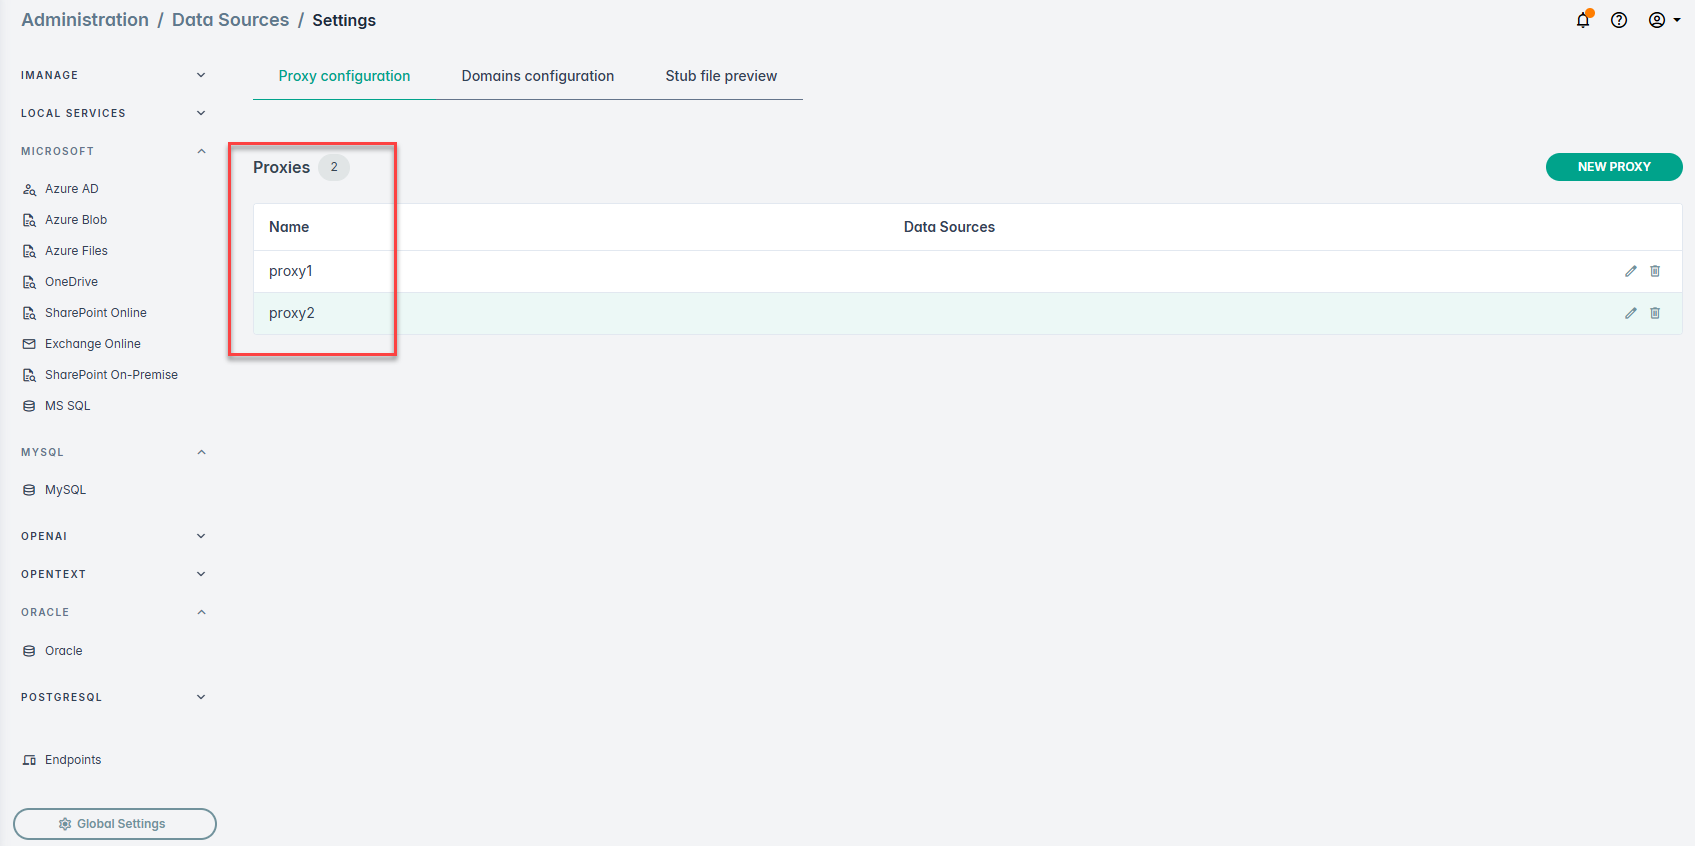
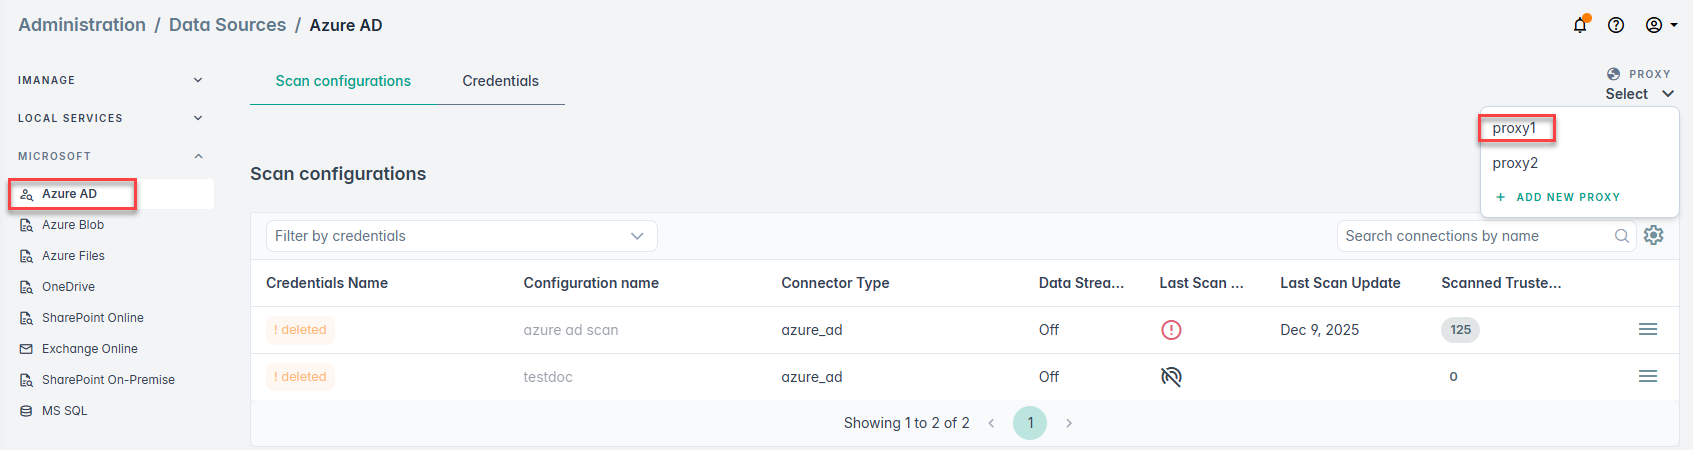
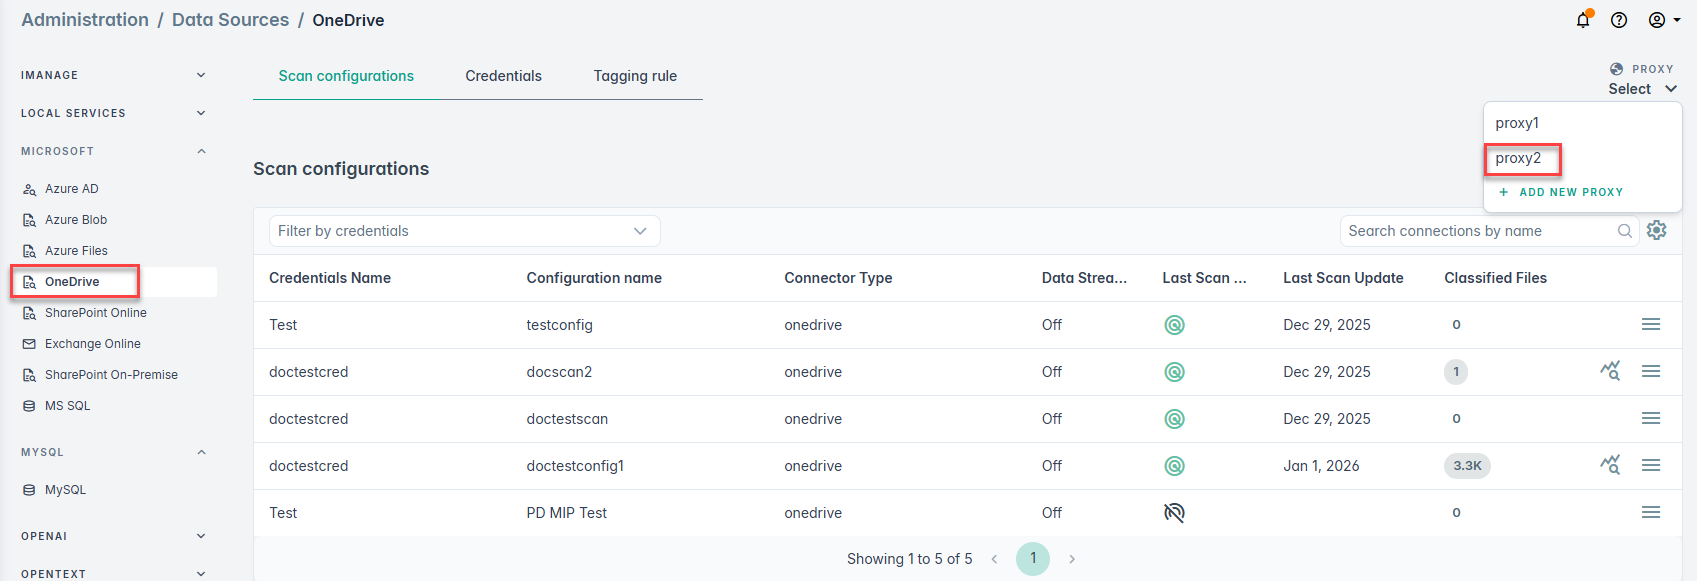
For detailed information, refer to the Global Settings section.
- SMTP Email Service for On‑Premises DSPM Customers
On-Premises DSPM customers can configure their own SMTP service for system email notifications, as an alternative to the existing Mailchimp integration. This gives customers full control over email delivery and aligns with internal compliance requirements.
For detailed information, refer to the Email Configuration section.
- iManage On‑Premises Support
DSPM can connect to on-premises iManage deployments for file scanning, trustee discovery, classification, and remediation actions. This extends DSPM's existing iManage Cloud support to cover customers running iManage on-premises - common in legal and professional services firms.
For detailed information, refer to the Registering an app for iManage on-premise section.
- Improvements to Detector Syncing, Visibility, and Customization
This release introduces major enhancements to detector management, visibility, and configuration, making it faster and easier to work with AI Mesh classifications.
Automatic Detector Sync
For on‑premises deployments, detectors automatically sync with the deployed AI Mesh. Any changes to the mesh—including custom or regional deployments—are reflected automatically, eliminating the need for QuickStart import or manual detector updates.
For SaaS deployments, detector behavior remains unchanged. Detectors must continue to be imported using QuickStart import, and automatic synchronization is not yet available. Support for auto sync in SaaS environments will be introduced in a future release.
Detector Enablement Behavior (Unchanged)
In 3.4, the change is limited to how detectors are imported (automatic vs. QuickStart import), not their enabled or disabled state. There is no change in detector enablement behaviour in 3.4 compared to 3.3.
- New users: Detectors are imported in an enabled state by default, consistent with the previous behaviour where detectors were imported enabled via QuickStart.
- Existing users: Previously configured detectors retain their existing enabled or disabled state after import. The system does not modify the state of detectors during import.
Users can see which detector group nodes each detector contributes to. Additionally, on the AI Mesh page, users can see which detector group nodes contribute to specific classification outcomes (tags).
This improved visibility provides a clearer end‑to‑end view of how detectors influence classification results, making it easier to understand and fine‑tune classification behaviour.
Bulk Enable/Disable Actions- Detector management is significantly faster with bulk enable and disable capabilities.
- This eliminates the need for time‑consuming, one‑by‑one updates when configuring multiple detectors.
Users can create custom detectors by selecting a Mesh detector group node directly, without requiring access to the Mesh manifest JSON or knowledge of detector group node naming conventions. When a node is selected, the detector name prefix is automatically prefilled, ensuring the detector is correctly associated with that node.
This association allows the detector to contribute to the classification outcomes linked to the selected detector group node, which can be verified on the AI Mesh page. This allows users to easily experiment with various custom detectors without depending on Forcepoint field support teams.
For detailed information, refer to the Detectors section.
Forcepoint DSPM 3.3
- Enhanced Out-of-the-Box (OOTB) AI Mesh for Unstructured Data
- Redesigned default AI Mesh (platform 3.3.x, mesh v3.20.0+) for simpler setup and fewer false positives.
- English only detectors with reduced default sensitivity for a cleaner OOTB experience.
- Expanded DLP policy support and a streamlined AI Mesh UI with improved visibility and navigation.
For detailed information, refer to the AI Mesh section.
- Enhancements to the DLP Policies Page
Starting with platform version 3.3. x, several updates have been introduced to improve flexibility and visibility when managing DLP policies.
Policies disabled by default
All DLP policies are disabled by default. Users can enable or disable policies selectively using the toggle button next to each listed policy. Only enabled policies will be applied to the extracted content during scans.
Improved policy management
The page now includes additional capabilities to simplify policy management.- Bulk changes: Users can enable or disable multiple policies at once and expand the Policy Group to view the rules with short description.
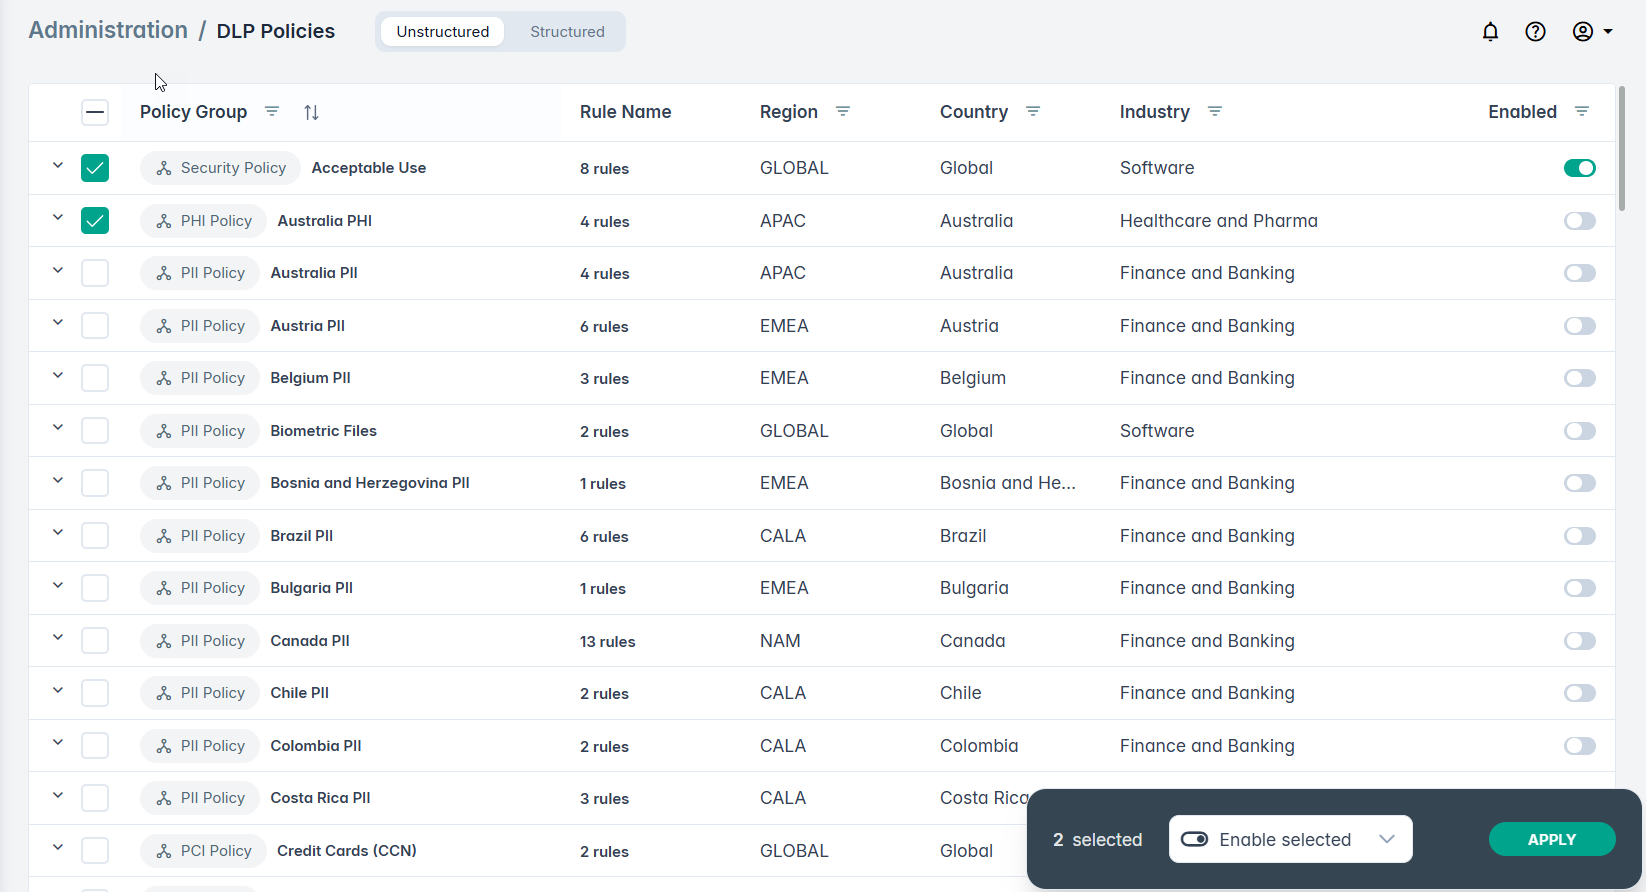
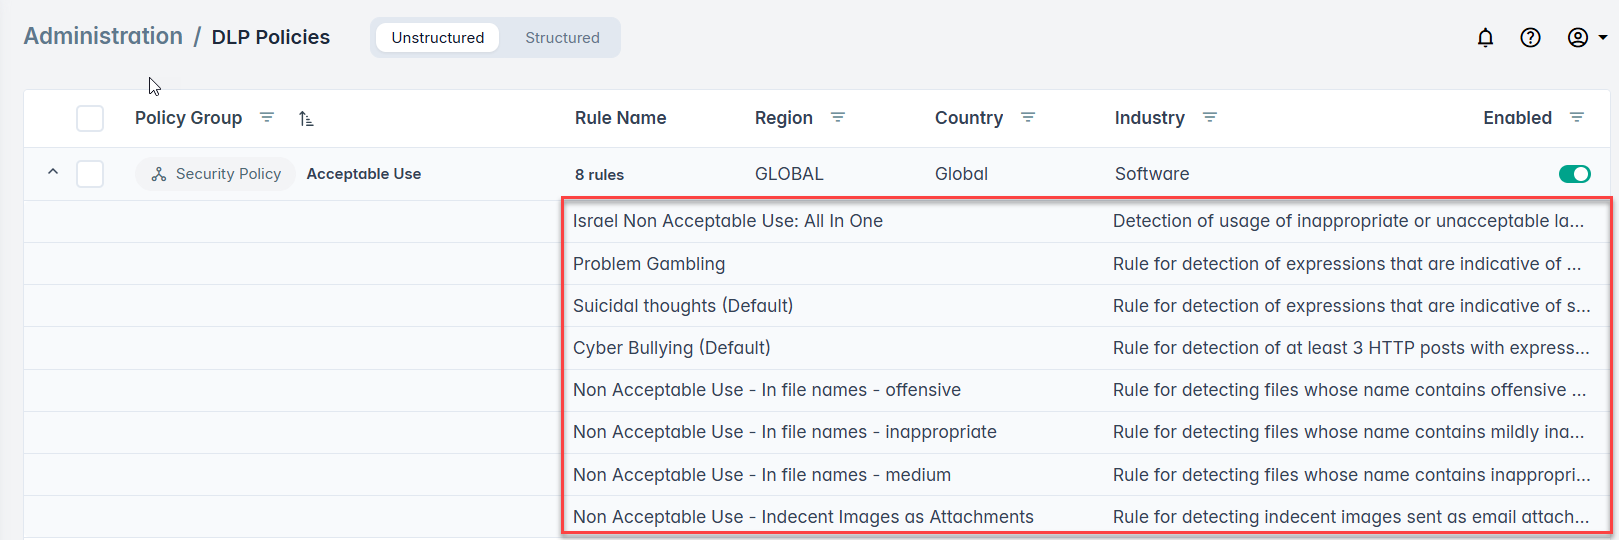
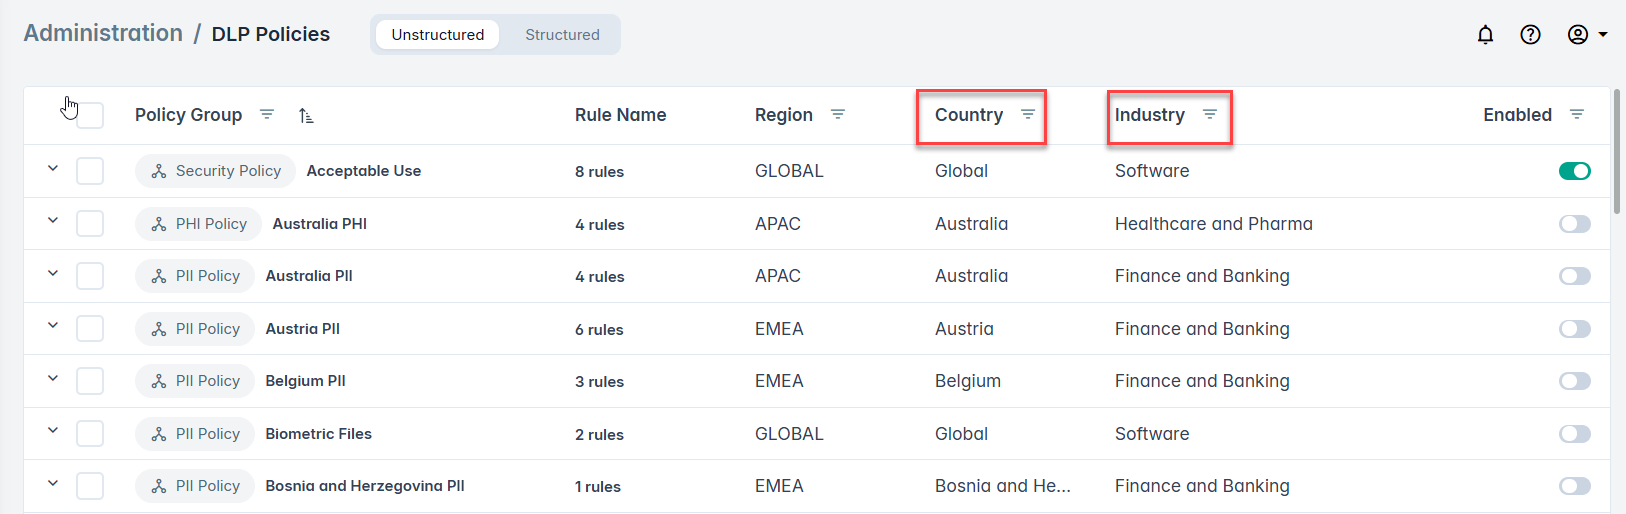
- New attributes: Policies can now be filtered and organized using additional metadata fields such as Country and Industry.
Expanded Policy coverage
The platform’s policy coverage has expanded with the number of available DLP policies increasing from 81 to 97, with the 16 newly added policies mapped to additional AI Mesh nodes and contributing indirectly to AIP (Classification) tags.
- Bulk changes: Users can enable or disable multiple policies at once and expand the Policy Group to view the rules with short description.
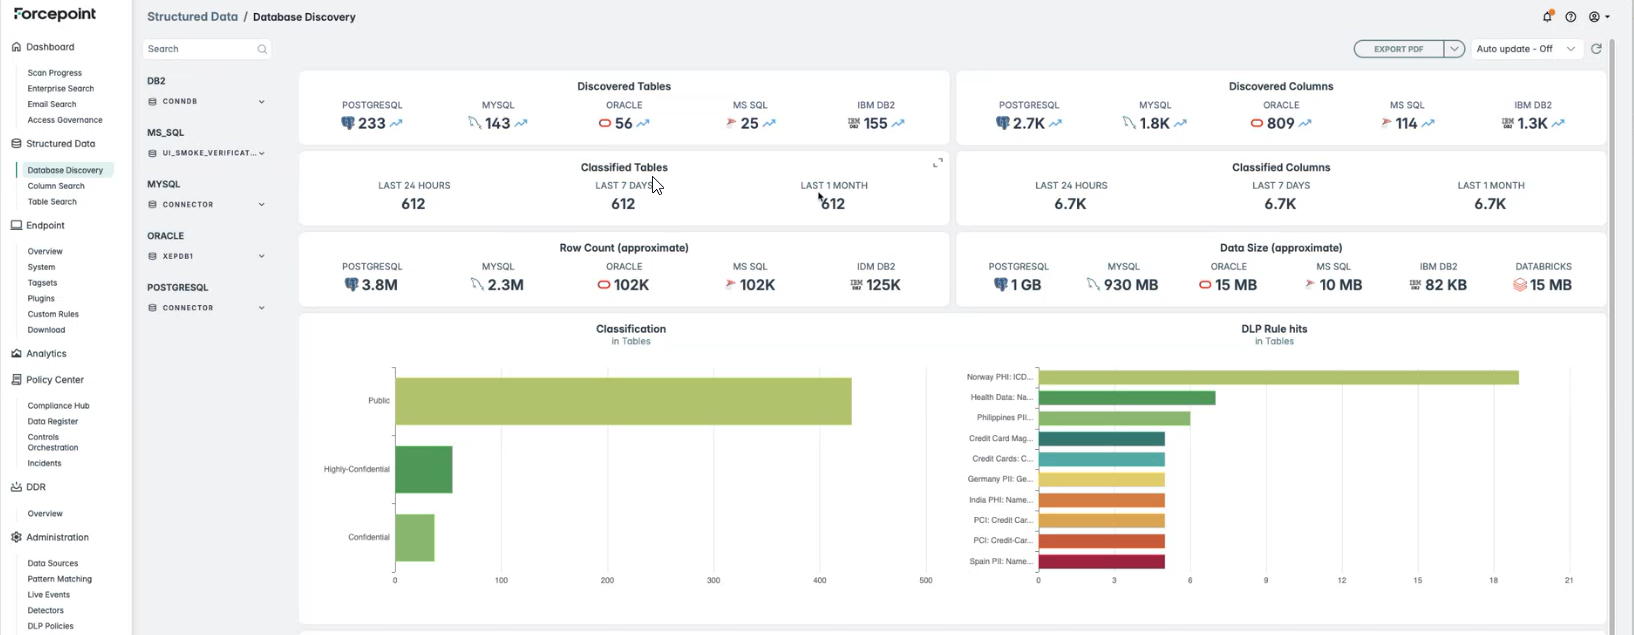
- Introducing Database Size Reporting
We have introduced enhanced reporting and visibility into database size metrics to support improved monitoring and capacity planning.
- Addition of Classification Overlays on ER diagram
We have added classification overlays and indicators directly to the ER diagram to enhance data discovery and support compliance workflows.
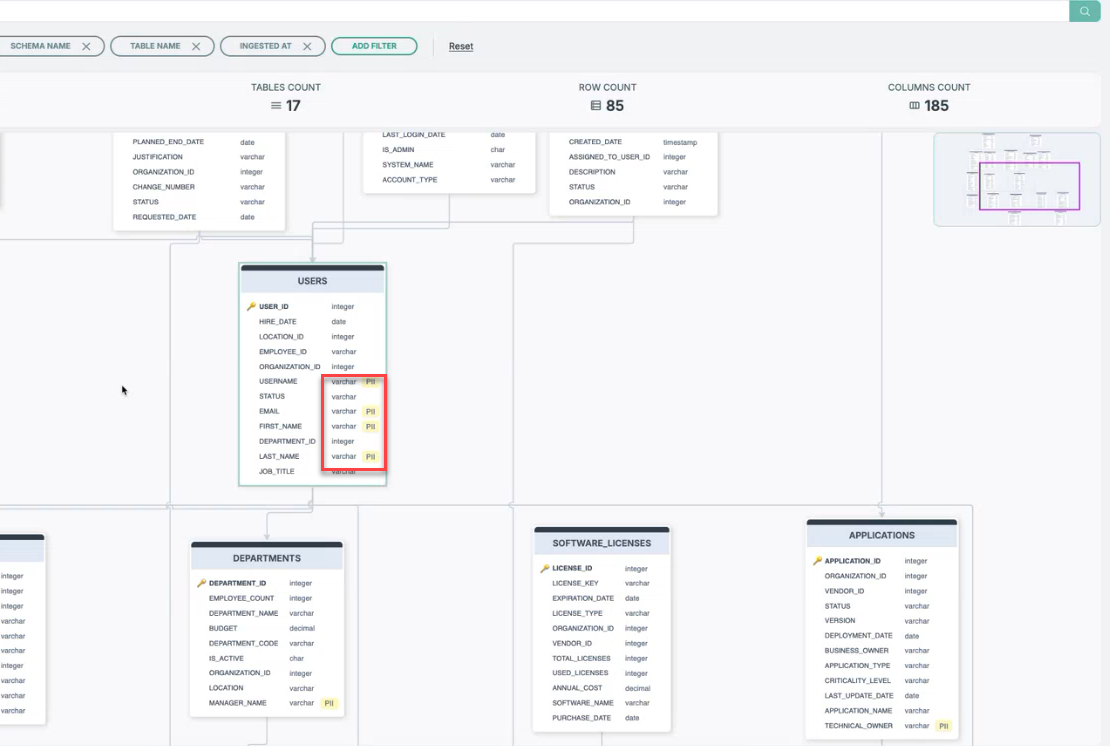 Note: Compliance Tags are applied for particular values as shown above.
- Empowering administrators with granular access control through Role Based Access Control (RBAC)
We have introduced Role Based Access Control (RBAC) to improve how access is managed across the system. RBAC lets administrators assign permissions based on roles, ensuring the right users have the right level of access.
Key Benefits- Stronger security and compliance through role based, consistent access control.
- Simplified and scalable user management using roles instead of individual permissions.
- Faster onboarding and offboarding with reduced administrative effort.
For detailed information, refer to the Role Based Access Control (RBAC) section.
Improved Credential Validation During Scan Execution
This update enhances the reliability of scan execution by improving how credential issues are detected and communicated.
Previously, credential validation occurred only during initial setup and when a scan configuration was created or started. If credentials became invalid during an active scan, the system did not detect the issue, leaving the scan in an In Progress state without notifying the user.
- The system now detects invalid credentials during active scans.
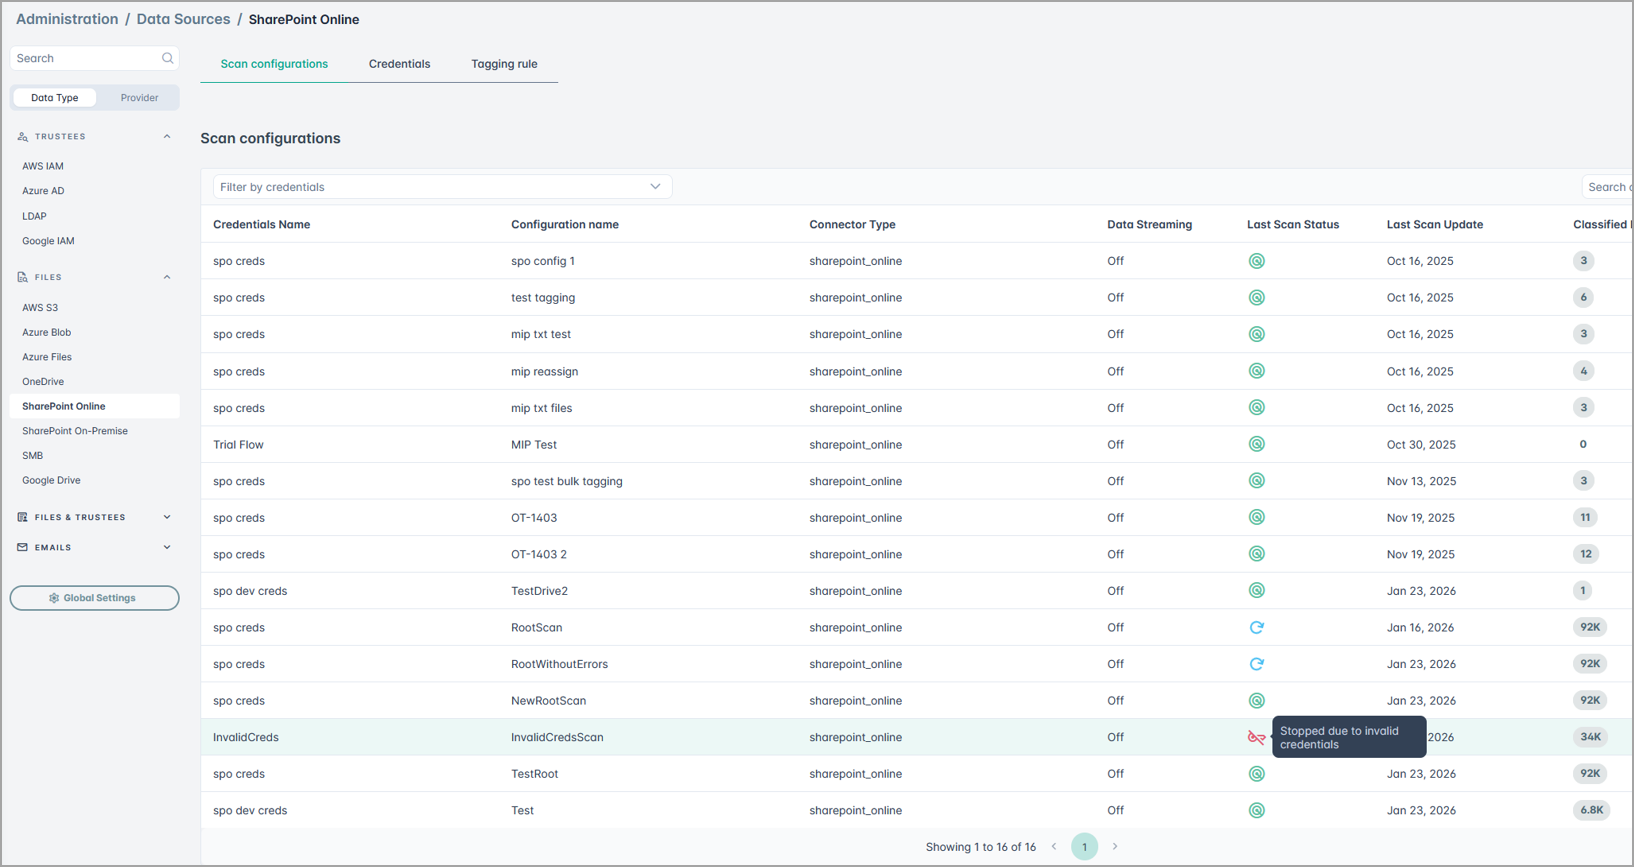
- Scans will no longer remain indefinitely in the In Progress state.
- Users are notified with clear error messages when credential failures occur.
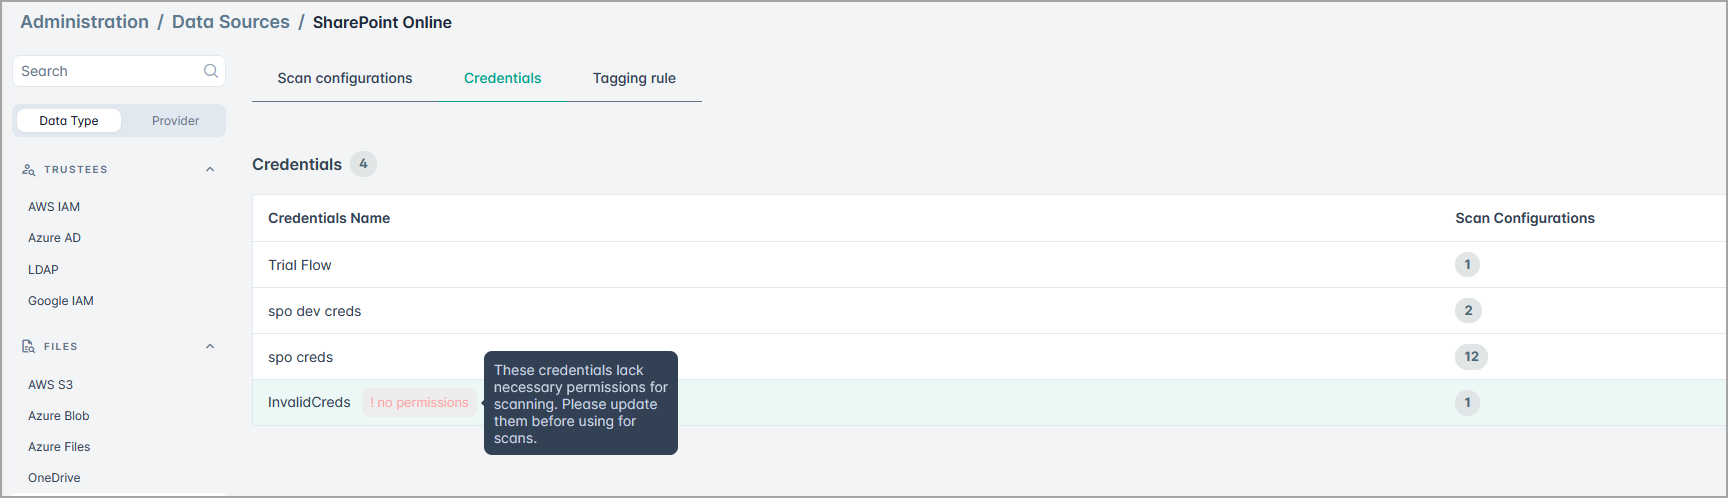
- Additionally, the system now restores the status and resumes the scan when the credentials become valid again.
These enhancements prevent unnecessary resource consumption, reduce stalled scans, and improve overall user experience and troubleshooting efficiency.
Extraction of user and permission details from structured data sources
We are introducing access governance for structured data, giving administrators a clear picture of which users and what type of permissions they have on a database. Administrators can easily view how many users have access, which schemas those users can reach, and which sensitive tables or columns are exposed.
When paired with data discovery and classification, this becomes even more powerful. If certain database accounts have access to sensitive information, administrators can quickly identify and investigate them. We also provide detailed insights into the specific permissions each user holds for every table. This makes it simpler to detect excessive privileges and take corrective action to maintain a least-privilege access model.
While creating a New Scan Configuration for structured data, you can now enable Fetch Permissions to collect access permission details for schemas, tables, and any shared settings before initiating the database scan or trustee scan either for the entire data source or for a specific path.
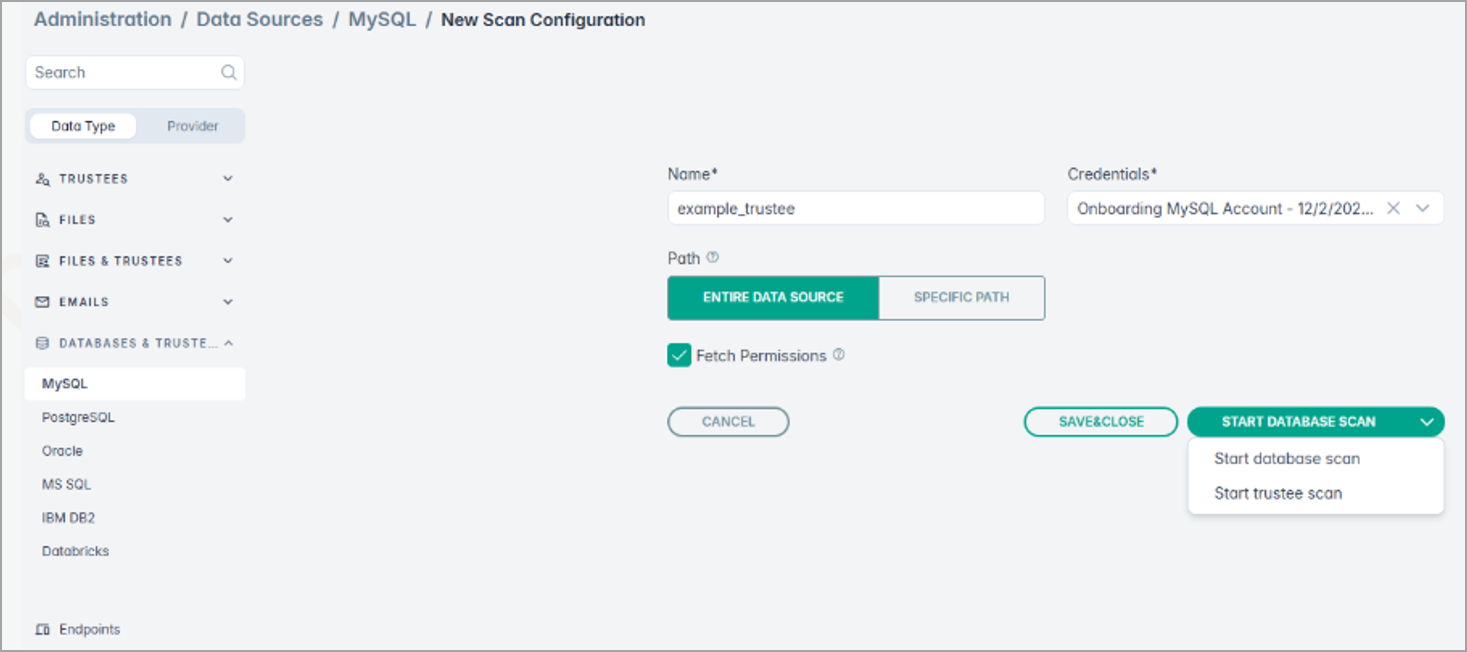
For detailed information, refer to Creating and Starting MySQL Scan Configuration section.
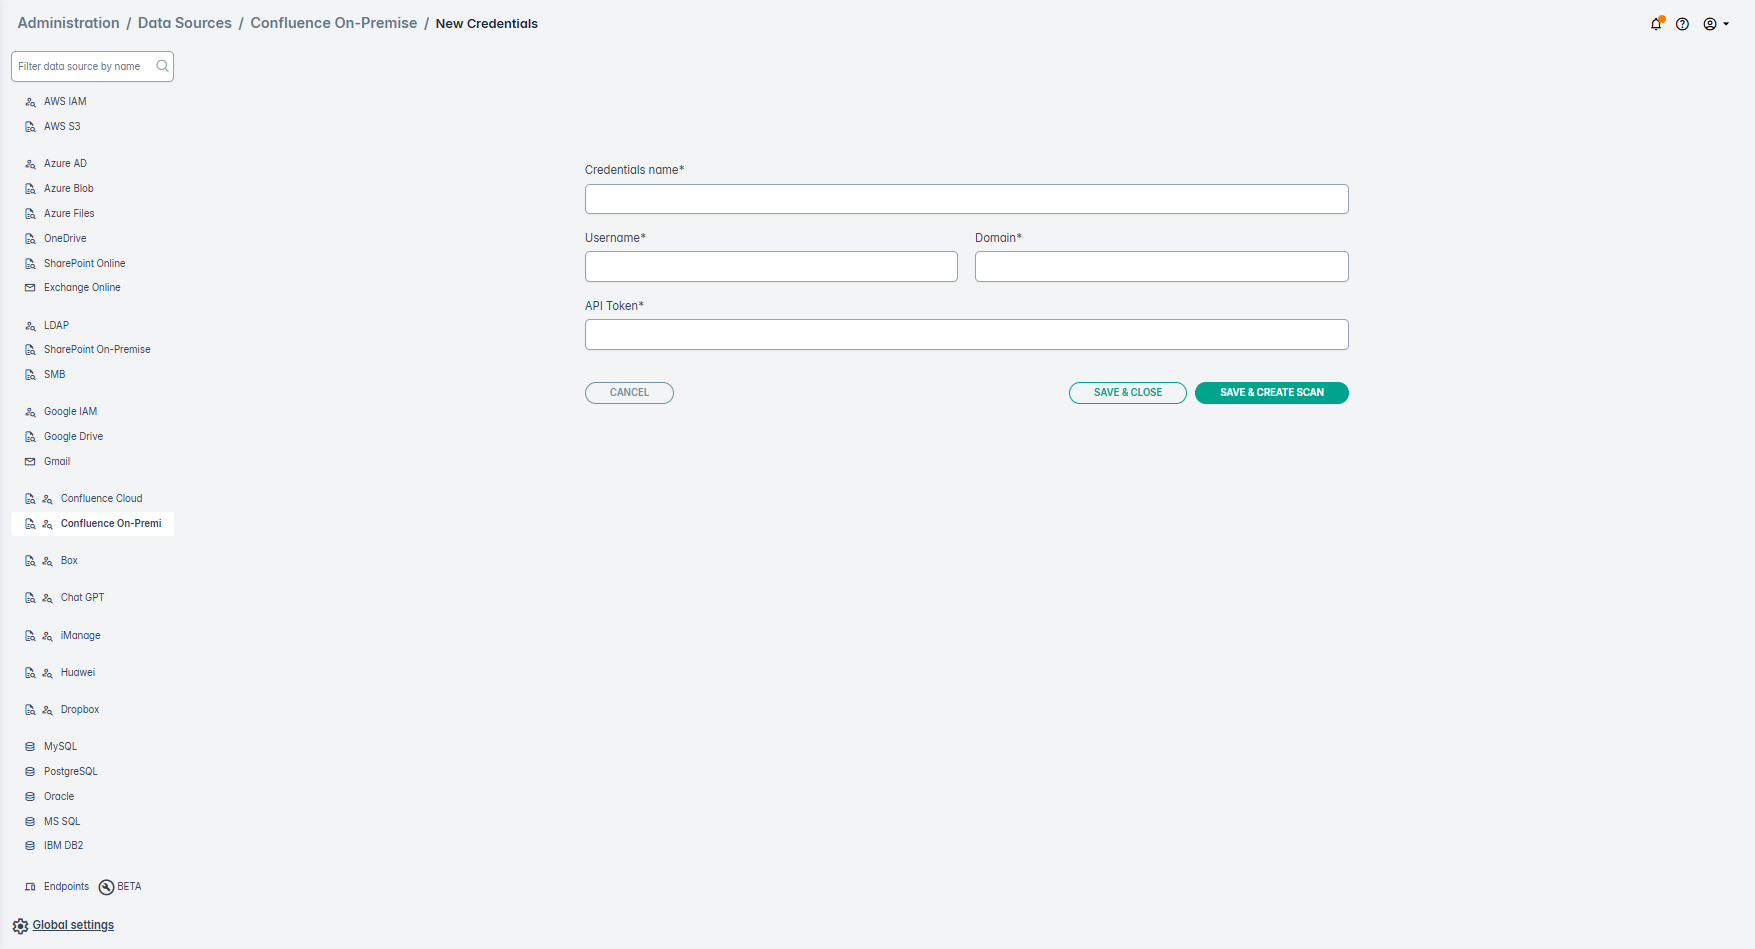
Confluence Server & Data Center Support
We now support scanning Confluence Server and Confluence Data Center instances, enabling customers to securely connect to their self-hosted environments.
This ensures sensitive data stored in Confluence can be discovered, classified, and protected — no matter where it's hosted. For details, see Confluence On-Premise.
Navigation Redesign
We’ve completely redesigned the main navigation to make it faster, more intuitive, and consistent across all Forcepoint products. The new layout offers a modern interface and enhanced usability, making it faster to access key features and information.
Highlights
- New sidebar layout: The main menu has moved from the top bar to a left-hand sidebar for better visibility and consistency.
- Unified experience: The navigation design now matches our other products, ensuring a seamless transition for users who work across multiple tools.
- Persistent navigation: The sidebar stays visible as you move between pages, improving usability.
- Collapsible left panel: The sidebar can now collapse into a minimalistic view with icons only, giving you more screen space while keeping navigation accessible.
- Breadcrumbs in header: Easily see where you are in the app with new breadcrumbs in the header section.
- Help icon relocation: The Help button has moved from “My Profile” to the header for easier access.
- Updated documentation links: All help links now point to Forcepoint-branded documentation pages.
- “What’s New” alert icon: The previous text link has been replaced with an alarm icon featuring an orange notification mark, so you never miss updates.
New Quick Start Guide
A newly designed Quick Start Guide is now available to help streamline the initial setup of DSPM. This wizard simplifies the process with fewer required options, an updated console, and the ability to select a connector and launch your first scan in just a few clicks. Once you complete the first few steps, it automatically navigates you to the data risk assessment report.
This feature provides the fastest path to value. The entire experience is designed to take you from initial setup to actionable risk reports in minutes. By guiding you seamlessly from connection to results, it eliminates complex configuration and empowers you to start exploring insights on your own data immediately.
For details, see Quick start.
Structured Data Support
Structured data support in Forcepoint DSPM extends data security posture management beyond unstructured environments, enabling organizations to discover, classify, and protect sensitive data residing in structured repositories such as databases, data warehouses, and cloud-native storage services.
We’ve extended DSPM support to structured databases using ODBC connectors. The initial release includes Oracle, MySQL, Microsoft SQL Server, PostgreSQL, and IBM DB2. Customers can now gain visibility and classification of sensitive data across tables, columns, and views, with the ability to override classifications as needed.
Structured data often holds an organization’s most sensitive assets—customer records, financial data, and IP—but has lacked unified visibility and controls. By extending AI Mesh Data Classification to structured sources, Forcepoint enables consistent discovery, classification, and policy enforcement across both structured and unstructured data.
For details, see Structured Data.
For customers requesting structured data support, field teams should email gv-ds@forcepoint.com with the following details so the Data Science team can enable tailored classifiers:
- Customer Name:
- Country:
- Customer Segment / Industry:
- Primary Use Case:
- Business Value / Expected Outcome:
- Structured Data Sources:
- Sample Volume:
- Classification labels:
- Classification taxonomy rules:
- Data Sensitivity / Compliance Requirements: Are there PII elements or special handling requirements (GDPR, HIPAA, etc.)?
This process will soon be replaced with a customer self-service quick start guide that enables relevant out-of-the-box classifiers for structured data.
Data Protection with Microsoft Purview Labels by writing classification tags as MIP labels to files stored on OneDrive and SharePoint Online
An option has been added that will apply classification results as MIP labels while tagging files stored in OneDrive or SharePoint Online.
This is a game-changer for data security. It directly connects our powerful data discovery and classification engine with Microsoft's native security enforcement tools. When DSPM classifies a file, it can now apply the corresponding Microsoft Purview MIP (sensitivity) label. This seamlessly triggers powerful, built-in security policies like file encryption and access restrictions (RMS), ensuring your most critical data in OneDrive and SharePoint is protected from the moment it is found and classified by the powerful AI-mesh.
Click the image below to view details:
Centralized Taxonomy Page
Centralized Taxonomy page within the Administration section. This new page serves as a single console for managing tags across both FDC and DSPM, making tag management consistent and efficient.
With this update, all tag creation, editing, and deletion tasks are now consolidated in the new Taxonomy page. The legacy pages in DSPM and FDC have been updated with redirect links to guide users to the new location.
Appropriate redirection and icons have been added from the FDC Tagset and Policy Center pages to this new Taxonomy page.
Key changes:
- Single console management – Tags for both FDC and DSPM can now be managed from one console.
- Streamlined actions – Create, edit, and delete tags exclusively from the new Taxonomy page.
- Updated legacy pages – The Taxonomy page in DSPM Policy Center has been deprecated, and tag modification options have been removed from the FDC Tagset page. Other Tagset functions in FDC remain available.
- Redirect support – Redirect links have been added in DSPM and FDC to help users move to the new page.
- No impact on existing tags – All current tags remain intact and accessible in the centralized page.
- Improved user experience – The new interface standardizes work flows, reduces duplication, and enhances governance.
For details, see Taxonomy.
Taxonomy label mapping
We’ve enhanced the way labels are handled during file scans and labeling processes. Previously, our system relied on hardcoded logic to define which labels to read and write, along with fixed mappings between our values and those in the data source.
With this update, customers gain greater visibility and control:
- Align AI Mesh taxonomy with the unique taxonomies used in your data sources. This ensures consistency and accuracy when applying classifications across different environments.
This improvement empowers organizations to bridge the gap between AI Mesh and their existing data source taxonomies, making classification more intuitive and adaptable. See Taxonomy.
Column audit log for structured data
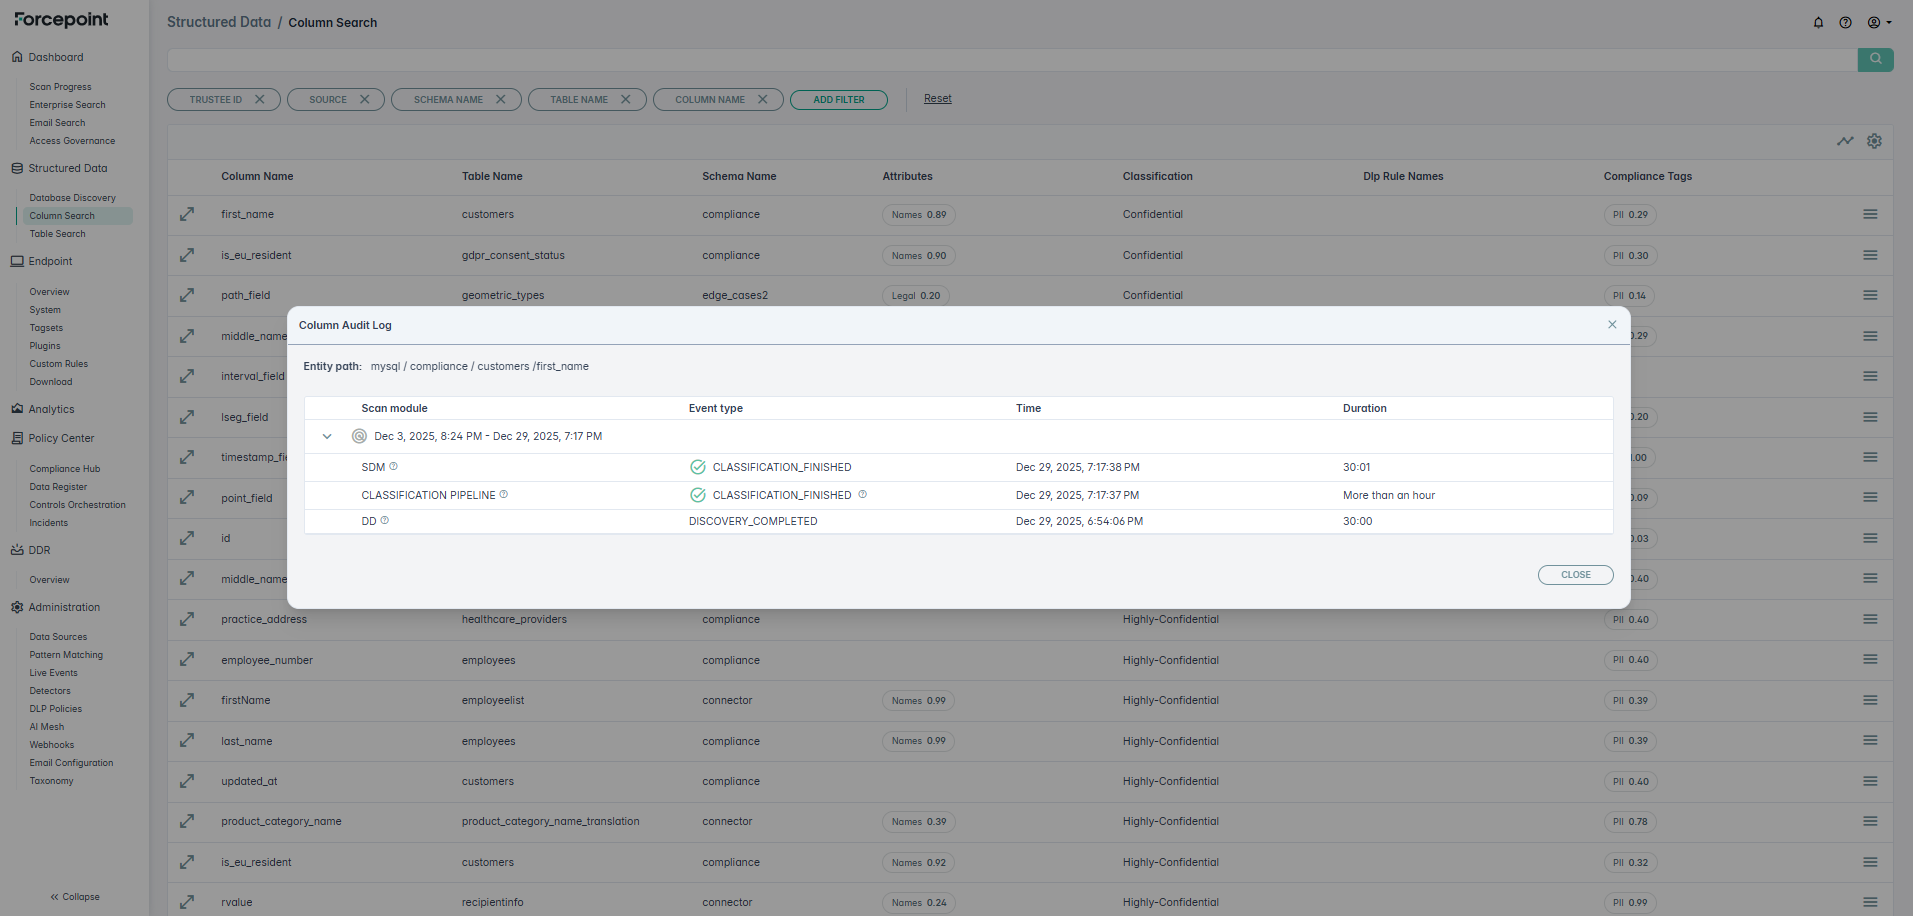
With the Column Log Audit feature, you can now view the details for each column after a database scan has been completed, by navigating to the Column Search section in the Structured Data section. You can view what stages of the classification pipeline completed and if there was any error that happened. See Column Search.
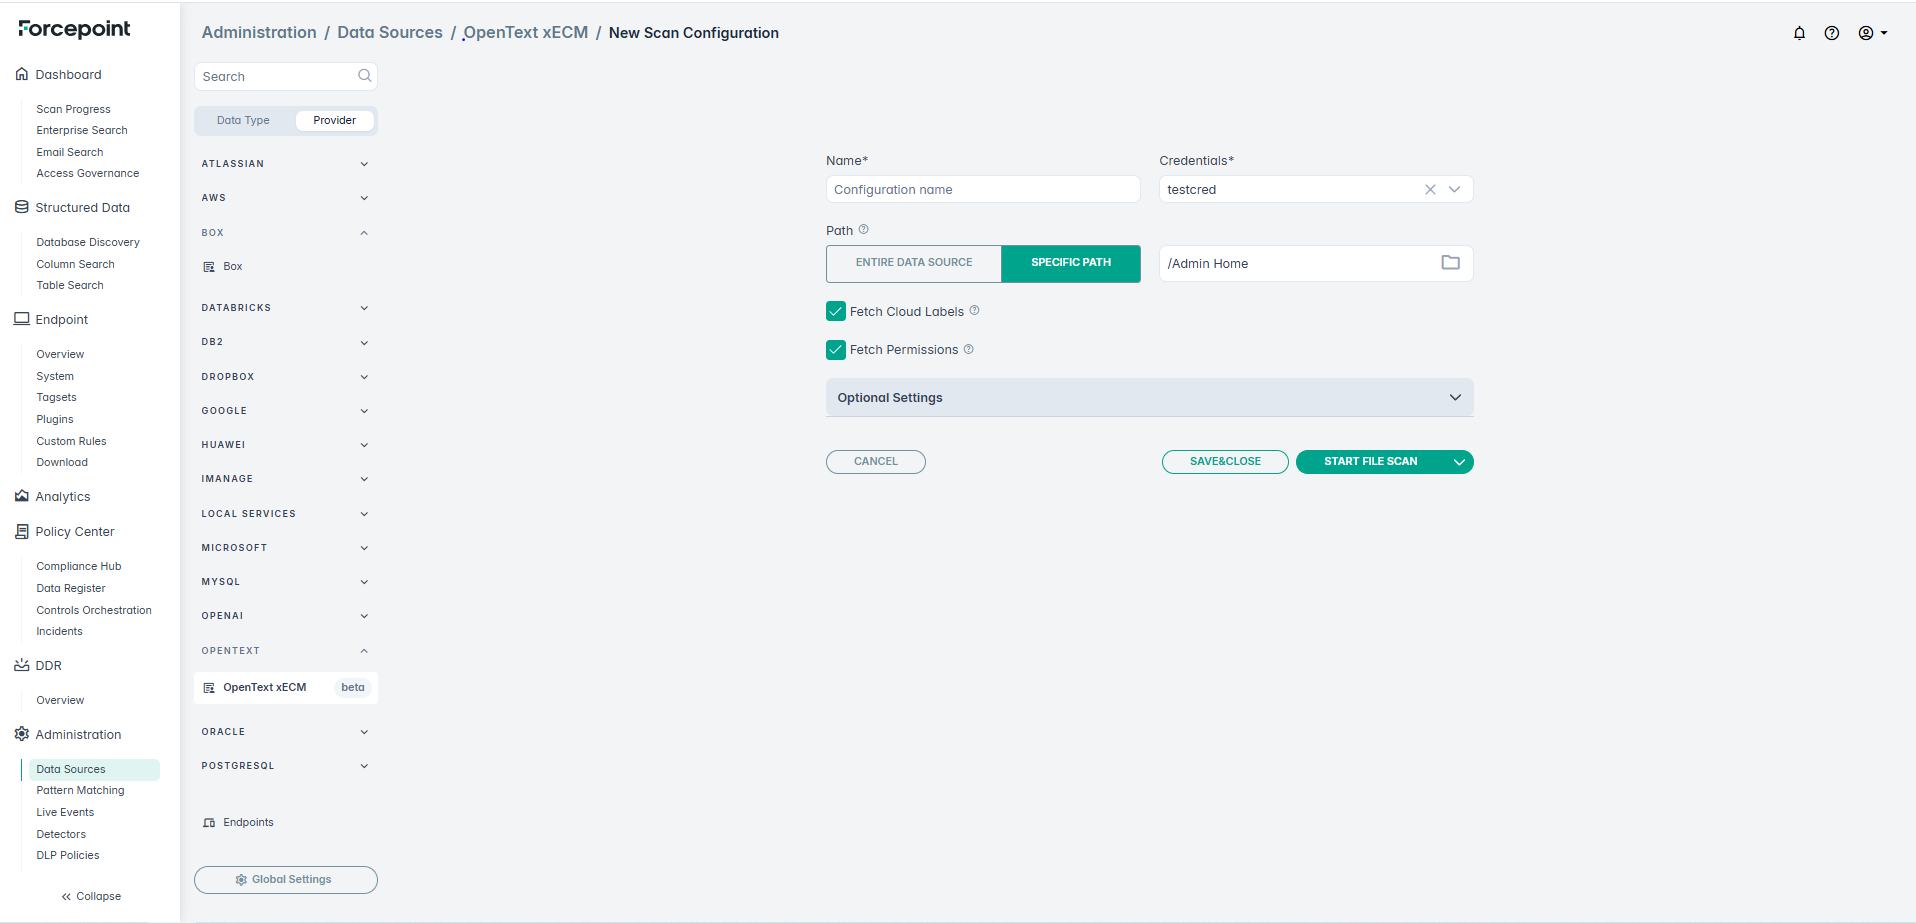
OpenText extended ECM connector beta
New data source connector is now supported for scanning OpenText data sources. See OpenText ECM section in the online help for details.
Granular Schema and Table Selection for Structured Data Scanning
Customers can now exercise greater control over structured data scans by either selecting schema only or specific tables within the schema for inclusion. This enhancement allows for more targeted and efficient data discovery.
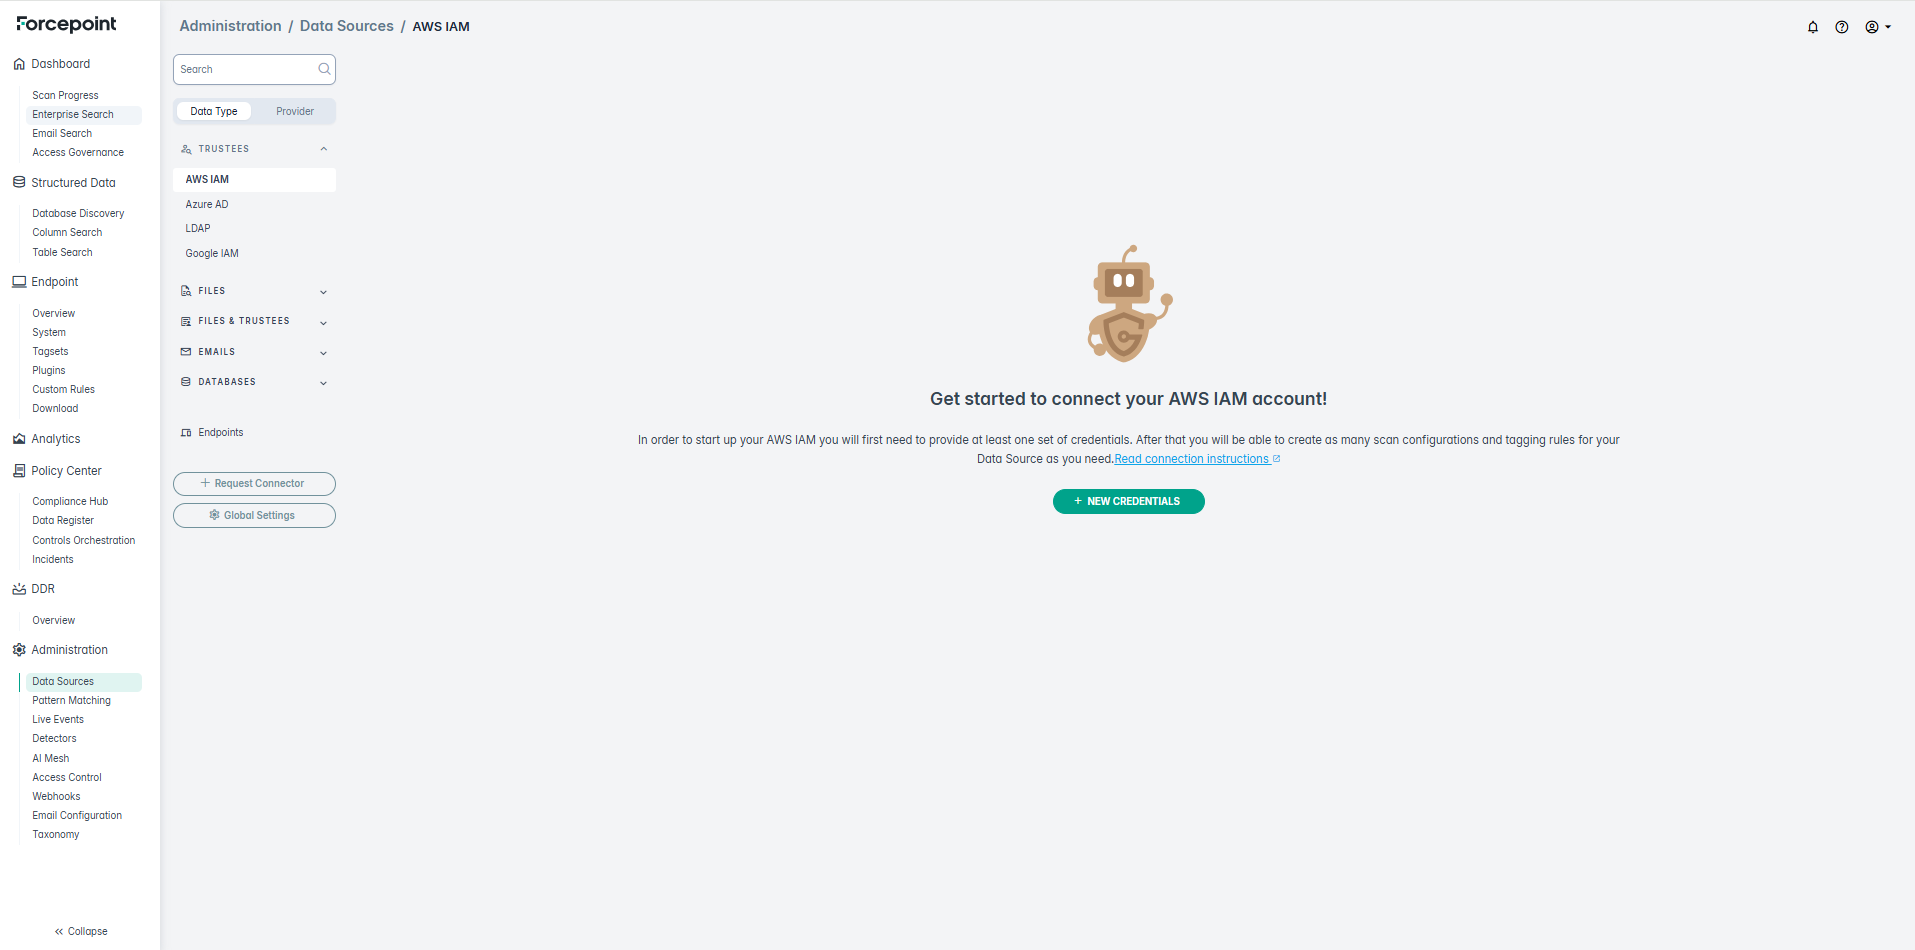
Redesign of additional layer of side menu
Redesign of additional layer of the side menu that helps you organize related items under broader categories.
- Modernized layout: A cleaner, more space-efficient design that improves readability and aligns with the new platform visual language. Quickly find the right data category without scrolling through a long list.
- Provider filtering: Quickly switch between Data Type and Provider views to find the data source you need.
- Simplified icons: Icons now represent data types rather than repeating for each item, reducing cognitive load.
The drag & drop feature for rearranging analytics boards is now clearly represented with a new handle icon, making it easier to discover and use.
GQL Syntax Highlighting
We have introduced full syntax highlighting to the GQL search bar. Different parts of the query - such as keys (e.g., source), values (e.g., GOOGLE_DRIVE), and operators (e.g., AND) are now automatically displayed in distinct colors and fonts.
This makes your queries significantly easier to read, write, and debug. You can now instantly distinguish between the components of your query, which helps you to build and read queries faster.